Qwen 3.8 Max Prime
Alibaba, closed weights, released Sep 2026, run at provider defaults through OpenRouter, served by Alibaba. It built the same five pages as every model on season 0.6.1 of the Rams Index, and Rams graded each one at desktop and phone size.
- Rank
- 24of 26 models by Index; the paired intervals allow 22 to 24
- Cost per page
- $0.34Generation only, list price on run day
- Earlier judges
- 84.8Under the grade sum this board used until 10/28, GPT-5.6 Terra placed it fourth of 26 and the Claude judge first.
- Grade sum
- 29.08Seven 1–5 grades, out of 35
- Pages judged
- 1010 judge passes, 2 builds per brief
- Defects per page
- 14.7Text under 12px (10 of 10)
Rank 24 of 26; the data allows anywhere from 22 to 24. Within noise of MiniMax M3 and Qwen 3.8 Max: the gap to each sits inside the noise, so the board can't order them yet. Clearly behind GPT-6.1 Sol, GPT-6 Astra, Grok 4.7, Claude Fable 5.1, GPT-6.1 Terra, GLM 5.3, Claude Opus 5.5, Claude Sonnet 5.5, Mistral Large 4, GPT-6 Luna, Claude Haiku 5.5, GPT-5.6 Sol, Claude Fable 5, Kimi K3, Kimi K3.1 Pro, GLM 5.3 Prime, DeepSeek V4 Pro, Claude Opus 4.8, MiMo V2.6 Pro, Gemini 4 Argon and Gemini 3.8 Flash. Clearly ahead of Muse Spark Open and Muse Wonder.
Grades by dimension
The seven grades behind the Index, 1 to 5, mean of desktop and phone. The tick is the mean across all 26 models.
Bars start at 2.8 and end at 4.6, the range the board uses, so small differences show.
Index by brief
The same Index on each of the five briefs, and where the model places on that brief among all 26.
Bars run from 0 to 100.
How it ran
Every model runs at its provider's default settings, through the same harness, with the same budget per page.
- Effort
- DefaultThe provider’s default. We send no effort or thinking setting
- Time per page
- 303sMedian over every build, broken ones included
- Output tokens
- 26.0kMedian per page, reasoning included
- Reasoning tokens
- 8.9kMedian per page, as the API reports them
- Broken pages
- 0 of 10Every build came back as a whole page
- Criticals
- 50%5 of 10 scored pages had a critical issue in their first Rams code review
- Built through
- OpenRouterServed by Alibaba
Best and worst page
Of its 10 judged pages, the one the judge graded highest and the one it graded lowest, with the judge's top findings on each, most severe first.
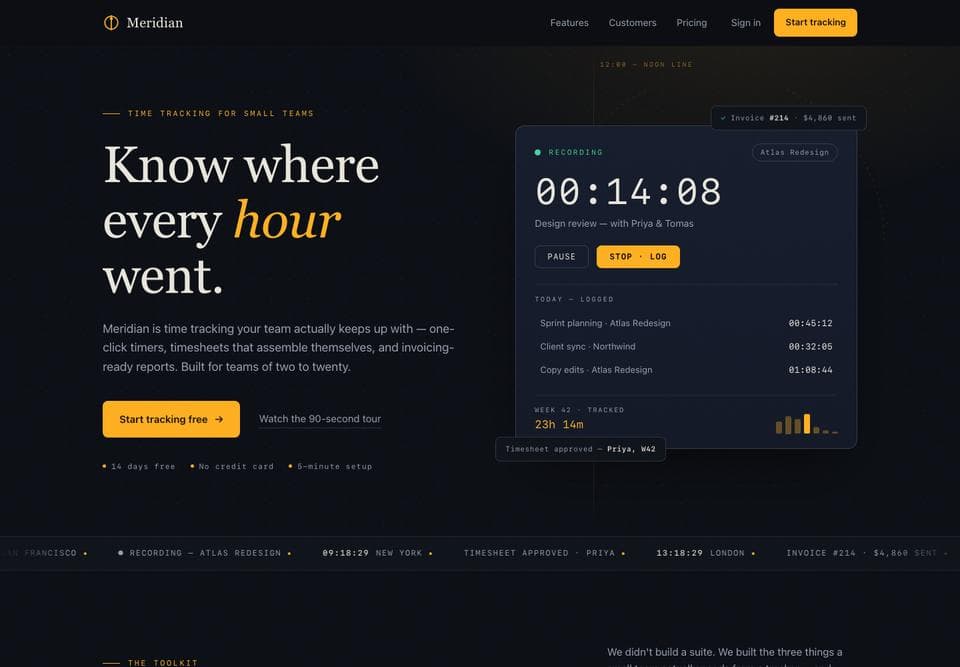
Best: Landing37.7
- Redundant content between ticker and hero card badgesModerate
- Subline paragraph sits unusually far below headlineModerate
- Invoice badge '#214' label and bold span visually gap mid-stringModerate
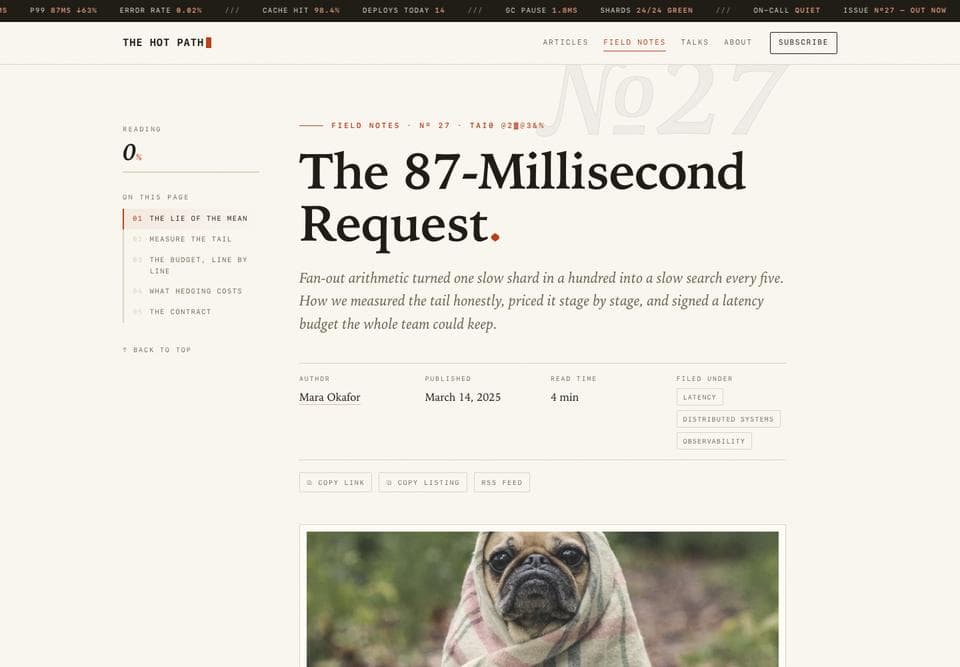
Worst: Article1.3
- Corrupted kicker textSerious
- Kicker text rendering corruptionSerious
- Reading-progress counter shows '0' at article top with no in-motion stateModerate


Head to head
Qwen 3.8 Max Prime against every other model: the paired difference in Index points, and whether the 95% interval on it clears zero.
- vs GPT-6.1 Sol-84.5Clearly behind
- vs GPT-6 Astra-83.5Clearly behind
- vs Grok 4.7-80.9Clearly behind
- vs Claude Fable 5.1-80.8Clearly behind
- vs GPT-6.1 Terra-78.6Clearly behind
- vs GLM 5.3-68.5Clearly behind
- vs Claude Opus 5.5-66.6Clearly behind
- vs Claude Sonnet 5.5-65.2Clearly behind
- vs Mistral Large 4-64.5Clearly behind
- vs GPT-6 Luna-63.7Clearly behind
- vs Claude Haiku 5.5-62.5Clearly behind
- vs GPT-5.6 Sol-61.4Clearly behind
- vs Claude Fable 5-55.3Clearly behind
- vs Kimi K3-54.5Clearly behind
- vs Kimi K3.1 Pro-50.8Clearly behind
- vs GLM 5.3 Prime-47.6Clearly behind
- vs DeepSeek V4 Pro-28.4Clearly behind
- vs Claude Opus 4.8-24.5Clearly behind
- vs MiMo V2.6 Pro-24.2Clearly behind
- vs Gemini 4 Argon-15.4Clearly behind
- vs Gemini 3.8 Flash-4.0Clearly behind
- vs MiniMax M3-3.3Inside the noise
- vs Qwen 3.8 Max-1.5Inside the noise
- vs Muse Spark Open+3.7Clearly better
- vs Muse Wonder+4.9Clearly better
The other models
Season 0.6.1 of the Rams Index, in board order.
- GPT-6.1 SolRank 1 · OpenAI92.0
- GPT-6 AstraRank 2 · OpenAI91.0
- Grok 4.7Rank 3 · SpaceXSI88.4
- Claude Fable 5.1Rank 4 · Anthropic88.3
- GPT-6.1 TerraRank 5 · OpenAI86.1
- GLM 5.3Rank 6 · Zhipu76.0
- Claude Opus 5.5Rank 7 · Anthropic74.1
- Claude Sonnet 5.5Rank 8 · Anthropic72.7
- Mistral Large 4Rank 9 · Mistral72.0
- GPT-6 LunaRank 10 · OpenAI71.2
- Claude Haiku 5.5Rank 11 · Anthropic70.0
- GPT-5.6 SolRank 12 · OpenAI68.9
- Claude Fable 5Rank 13 · Anthropic62.8
- Kimi K3Rank 14 · Moonshot62.0
- Kimi K3.1 ProRank 15 · Moonshot58.3
- GLM 5.3 PrimeRank 16 · Zhipu55.1
- DeepSeek V4 ProRank 17 · DeepSeek35.9
- Claude Opus 4.8Rank 18 · Anthropic32.0
- MiMo V2.6 ProRank 19 · Xiaomi31.7
- Gemini 4 ArgonRank 20 · Google22.9
- Gemini 3.8 FlashRank 21 · Google11.5
- MiniMax M3Rank 22 · MiniMax10.8
- Qwen 3.8 MaxRank 23 · Alibaba9.0
- Muse Spark OpenRank 25 · Meta3.8
- Muse WonderRank 26 · Meta2.6

Frameworks