Claude Opus 4.8
Anthropic, closed weights, released May 2026, run at provider defaults through the Anthropic API. It built the same five pages as every model on season 0.5 of the Rams Index, and Rams graded each one at desktop and phone size.
- Rank
- 14of 14 models by Index; the paired intervals allow 12 to 14
- Cost per page
- $0.15Generation only, list price on run day
- Second judge
- 69.5GPT-5.6 Terra places it 14th of 14. The Claude judge: 14th.
- Grade sum
- 21.80Seven 1–5 grades, out of 35
- Pages judged
- 1520 judge passes, 3 builds per brief
- Defects per page
- 2.5Content wider than the phone (9 of 15)
Rank 14 of 14; the data allows anywhere from 12 to 14. Within noise of Gemini 3.8 Flash and DeepSeek V4 Pro: the gap to each sits inside the noise, so the board can't order them yet. Clearly behind GPT-6 Astra, Grok 4.7, GPT-6.1 Sol, Claude Sonnet 5.5, GPT-6 Luna, Gemini 4 Argon, Muse Wonder, Claude Opus 5.5, GPT-5.6 Sol, Claude Fable 5.1 and Claude Fable 5. Not clearly ahead of any model.
Grades by dimension
The seven grades behind the Index, 1 to 5, mean of desktop and phone. The tick is the mean across all 14 models.
Bars start at 2.8 and end at 4.2, the range the board uses, so small differences show.
Index by brief
The same Index on each of the five briefs, and where the model places on that brief among all 14.
Bars run from 40 to 90.
How it ran
Every model runs at its provider's default settings, through the same harness, with the same budget per page.
- Effort
- DefaultThe provider’s default. We send no effort or thinking setting
- Time per page
- 61sMedian over every build, broken ones included
- Output tokens
- 6.2kMedian per page, reasoning included
- Reasoning tokens
- n/aIts API doesn’t report them separately
- Broken pages
- 0 of 15Every build came back as a whole page
- Criticals
- 33%5 of 15 scored pages had a critical issue in their first Rams code review
- Built through
- Anthropic APIServed by Anthropic
Best and worst page
Of its 15 judged pages, the one the judge graded highest and the one it graded lowest, with the judge's top findings on each, most severe first.
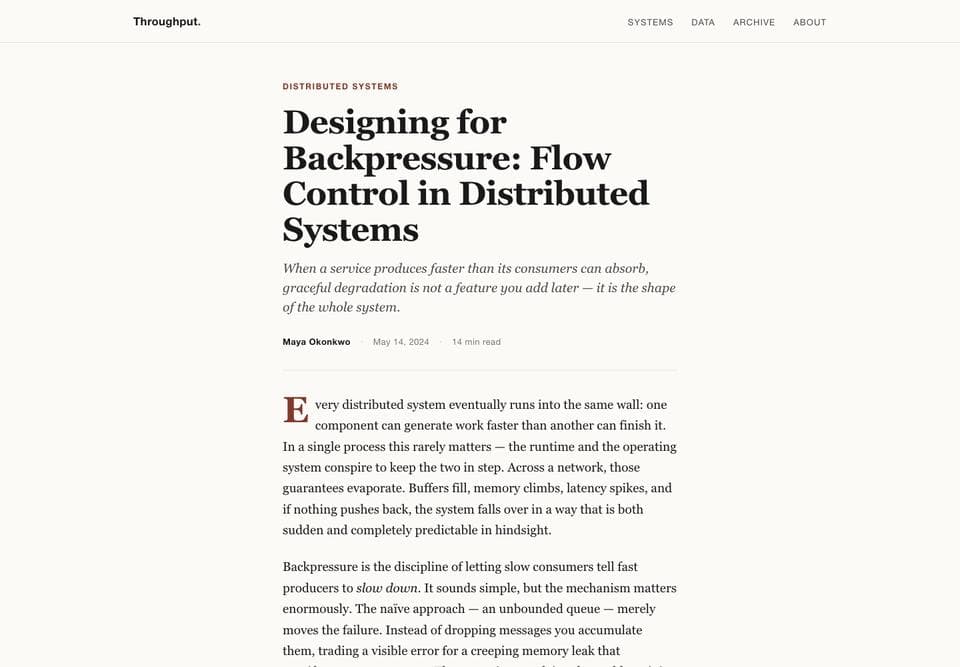
Best: Article73.2
- Drop cap 'E' visually heavy but unrefinedModerate
- Blockquote left border creates slightly tight internal paddingModerate
- Cite attribution in pullquote competes with quote weightModerate
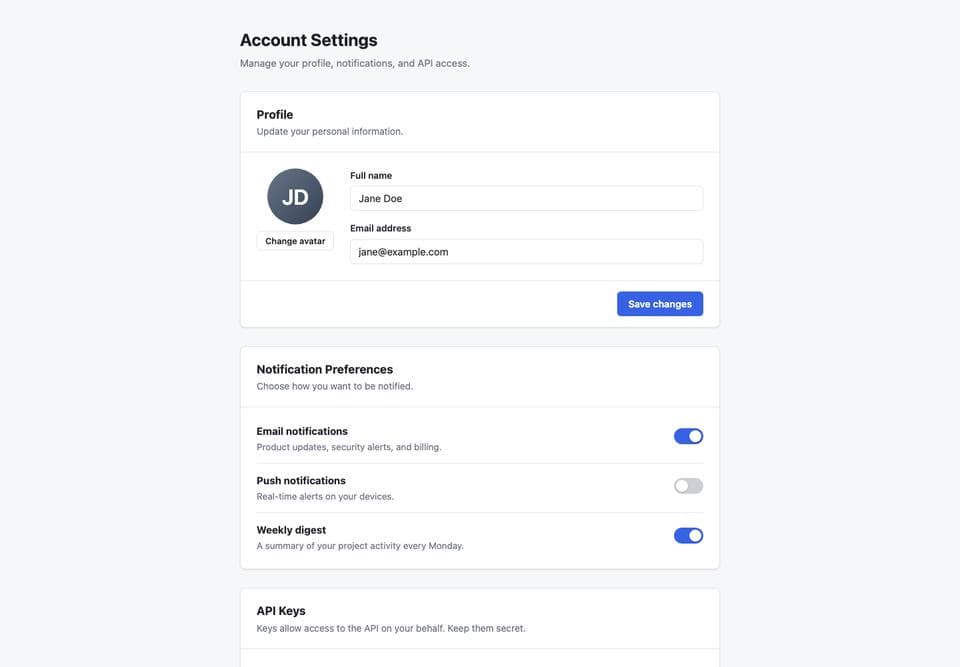
Worst: Settings45.5
- Inconsistent button styles across sectionsSerious
- Inconsistent button treatment across same-level actionsSerious
- Avatar block and form fields misaligned vertically in profile rowSerious
All 15 of its pages sit beside every other model's in the gallery.
Head to head
Claude Opus 4.8 against every other model: the paired difference in Index points, and whether the 95% interval on it clears zero.
- vs GPT-6 Astra-13.6Clearly behind
- vs Grok 4.7-13.2Clearly behind
- vs GPT-6.1 Sol-12.5Clearly behind
- vs Claude Sonnet 5.5-8.9Clearly behind
- vs GPT-6 Luna-8.9Clearly behind
- vs Gemini 4 Argon-8.8Clearly behind
- vs Muse Wonder-7.7Clearly behind
- vs Claude Opus 5.5-7.5Clearly behind
- vs GPT-5.6 Sol-6.1Clearly behind
- vs Claude Fable 5.1-6.1Clearly behind
- vs Claude Fable 5-4.8Clearly behind
- vs Gemini 3.8 Flash-2.7Inside the noise
- vs DeepSeek V4 Pro-1.8Inside the noise
The other models
Season 0.5 of the Rams Index, in board order, then the unranked.
- GPT-6 AstraRank 1 · OpenAI66.4
- Grok 4.7Rank 2 · SpaceXSI66.1
- GPT-6.1 SolRank 3 · OpenAI65.4
- Claude Sonnet 5.5Rank 4 · Anthropic61.8
- GPT-6 LunaRank 5 · OpenAI61.8
- Gemini 4 ArgonRank 6 · Google61.6
- Muse WonderRank 7 · Meta60.5
- Claude Opus 5.5Rank 8 · Anthropic60.4
- GPT-5.6 SolRank 9 · OpenAI58.9
- Claude Fable 5.1Rank 10 · Anthropic58.9
- Claude Fable 5Rank 11 · Anthropic57.6
- Gemini 3.8 FlashRank 12 · Google55.5
- DeepSeek V4 ProRank 13 · DeepSeek54.6
- Qwen 3.8 MaxUnranked · Alibaba
- Kimi K3Unranked · Moonshot
- GLM 5.3Unranked · Zhipu

Frameworks