Claude Haiku 5.5
Anthropic, closed weights, released Oct 2026, run at provider defaults through OpenRouter, served by Anthropic. It built the same five pages as every model on season 0.6.1 of the Rams Index, and Rams graded each one at desktop and phone size.
- Rank
- 13of 26 models by Index; the paired intervals allow 7 to 16
- Cost per page
- $0.006Generation only, list price on run day
- Tier
- MiddleClearly behind at least one model
- Pages judged
- 1010 judge passes, 2 builds per brief
- Defects per page
- 3.1Tap targets under 24px on the phone (7 of 10)
Rank 13 of 26; the data allows anywhere from 7 to 16. Within noise of Mistral Large 4, GLM 5.3, Claude Sonnet 5.5, GPT-5.6 Sol, GPT-6 Luna, Kimi K3, Kimi K3.1 Pro, GLM 5.3 Prime and Claude Fable 5: the gap to each sits inside the noise, so the board can't order them yet. Clearly behind 6 models. Clearly ahead of 10 models.
Grades by dimension
The seven grades behind the Index, 1 to 5, mean of desktop and phone. The tick is the mean across all 26 models.
Bars start at 2.8 and end at 4.6, the range the board uses, so small differences show.
Index by brief
The same Index on each of the five briefs, and where the model places on that brief among all 26.
Bars run from 0 to 100.
How it ran
Every model runs at its provider's default settings, through the same harness, with the same budget per page.
- Effort
- DefaultThe provider’s default. We send no effort or thinking setting
- Time per page
- 52sMedian over every build, broken ones included
- Output tokens
- 11.3kMedian per page, reasoning included
- Reasoning tokens
- 0.7kMedian per page, as the API reports them
- Broken pages
- 0 of 10Every build came back as a whole page
- Criticals
- 0%0 of 10 scored pages had a critical issue in their first Rams code review
- Built through
- OpenRouterServed by Anthropic
Best and worst page
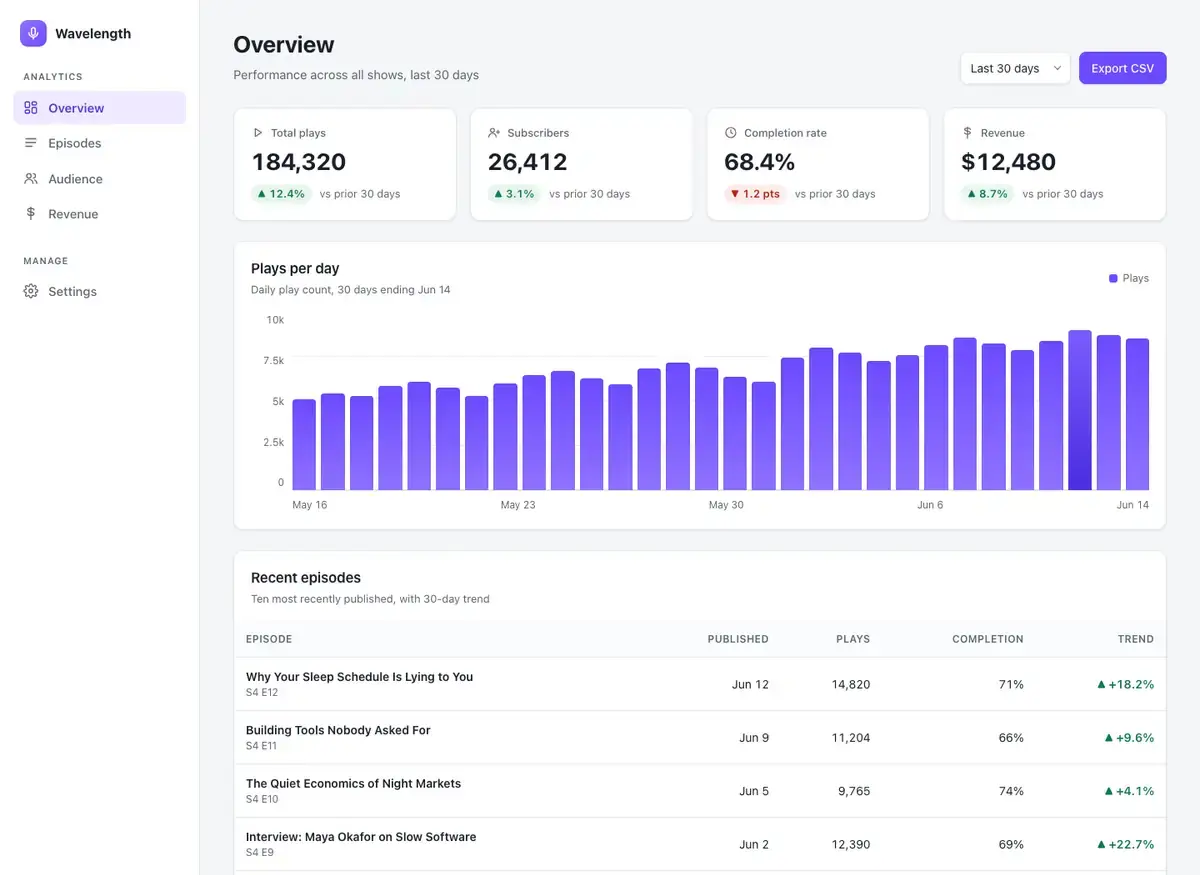
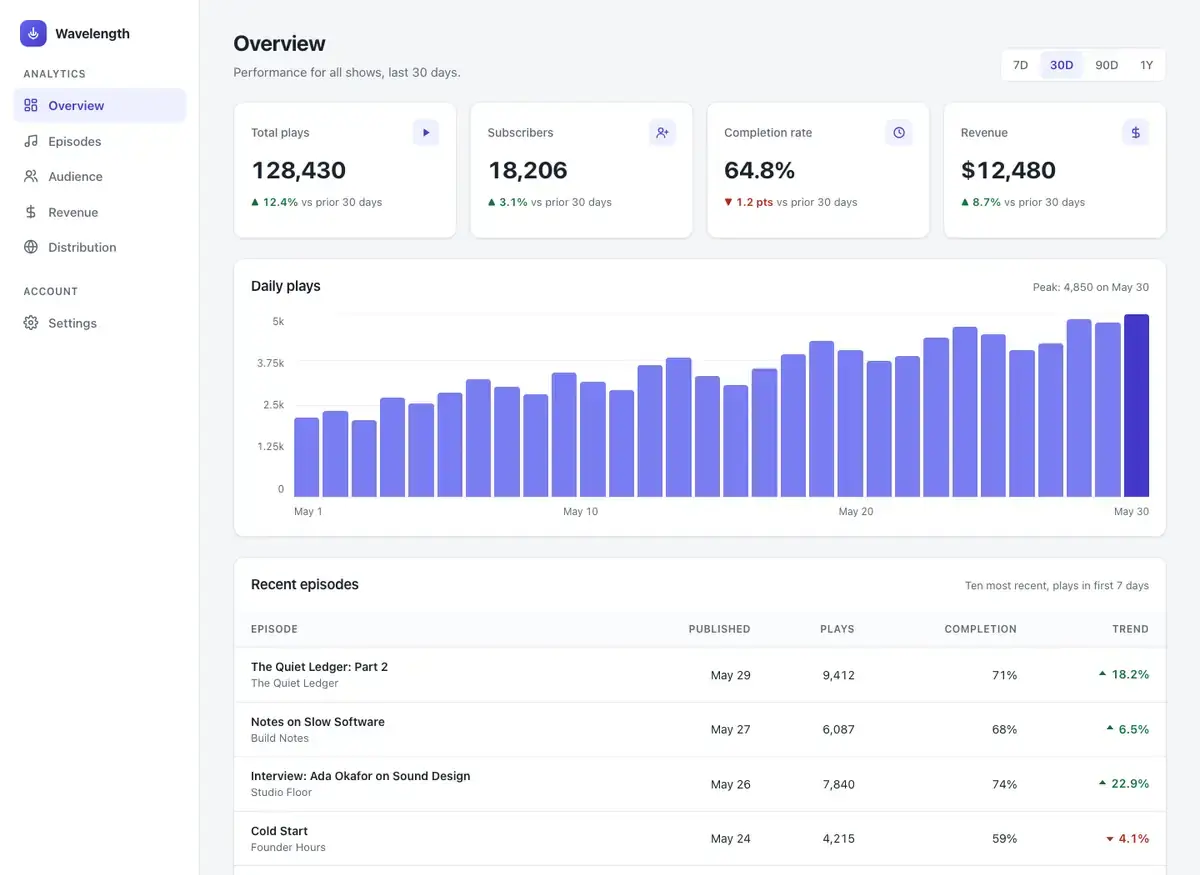
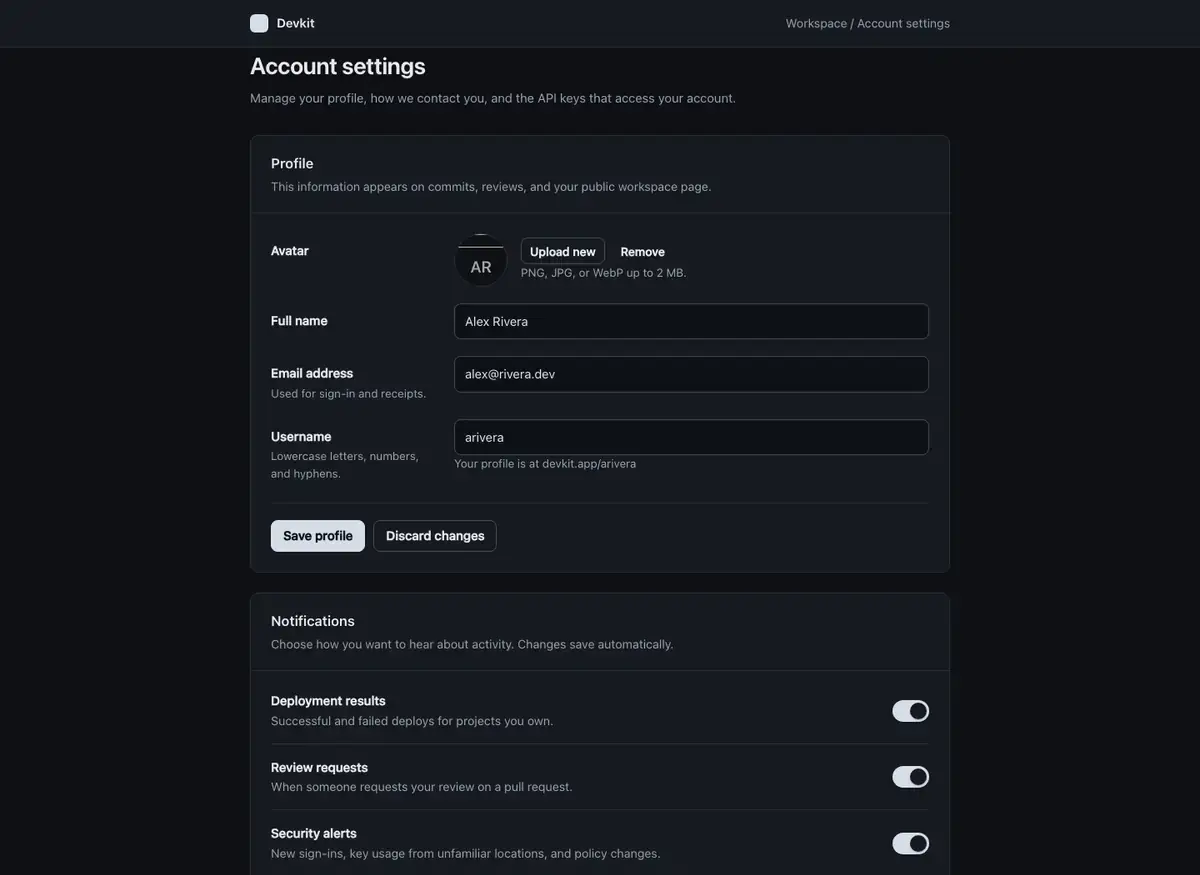
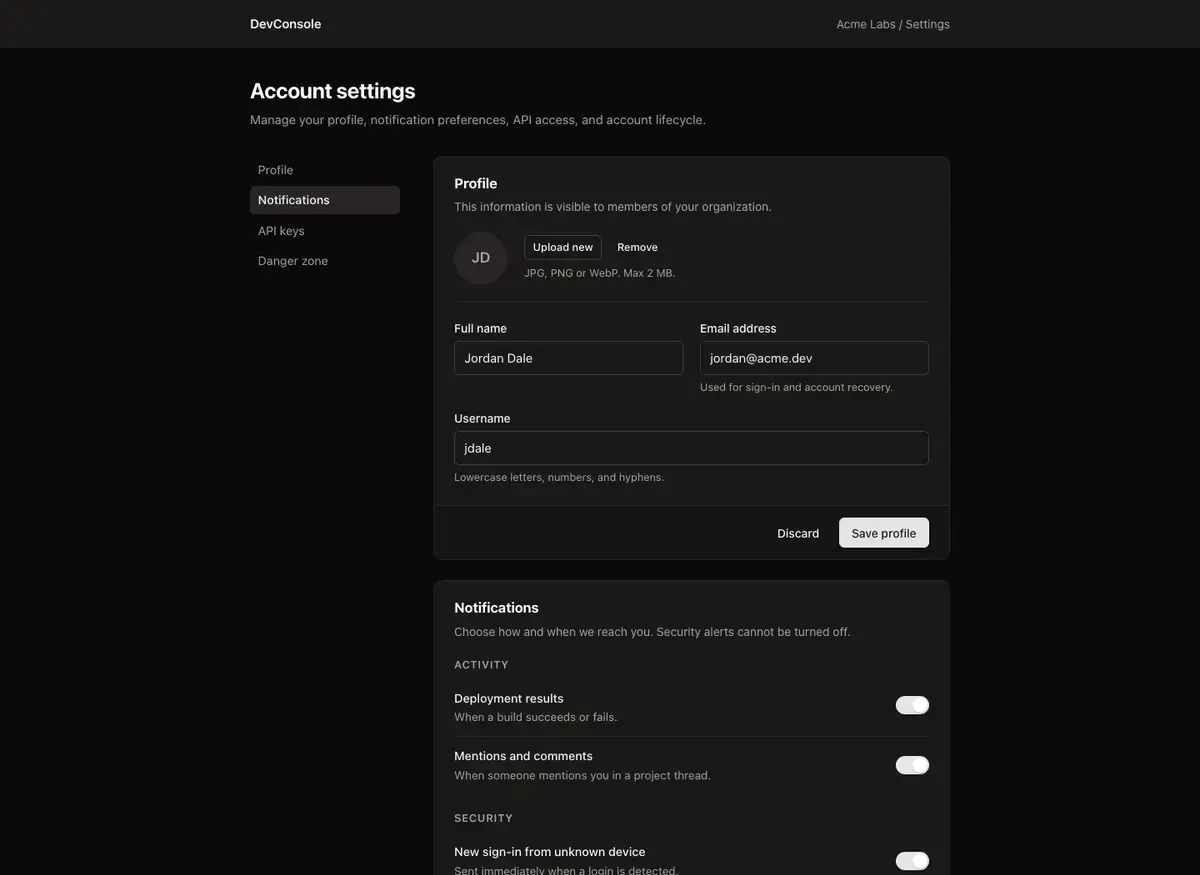
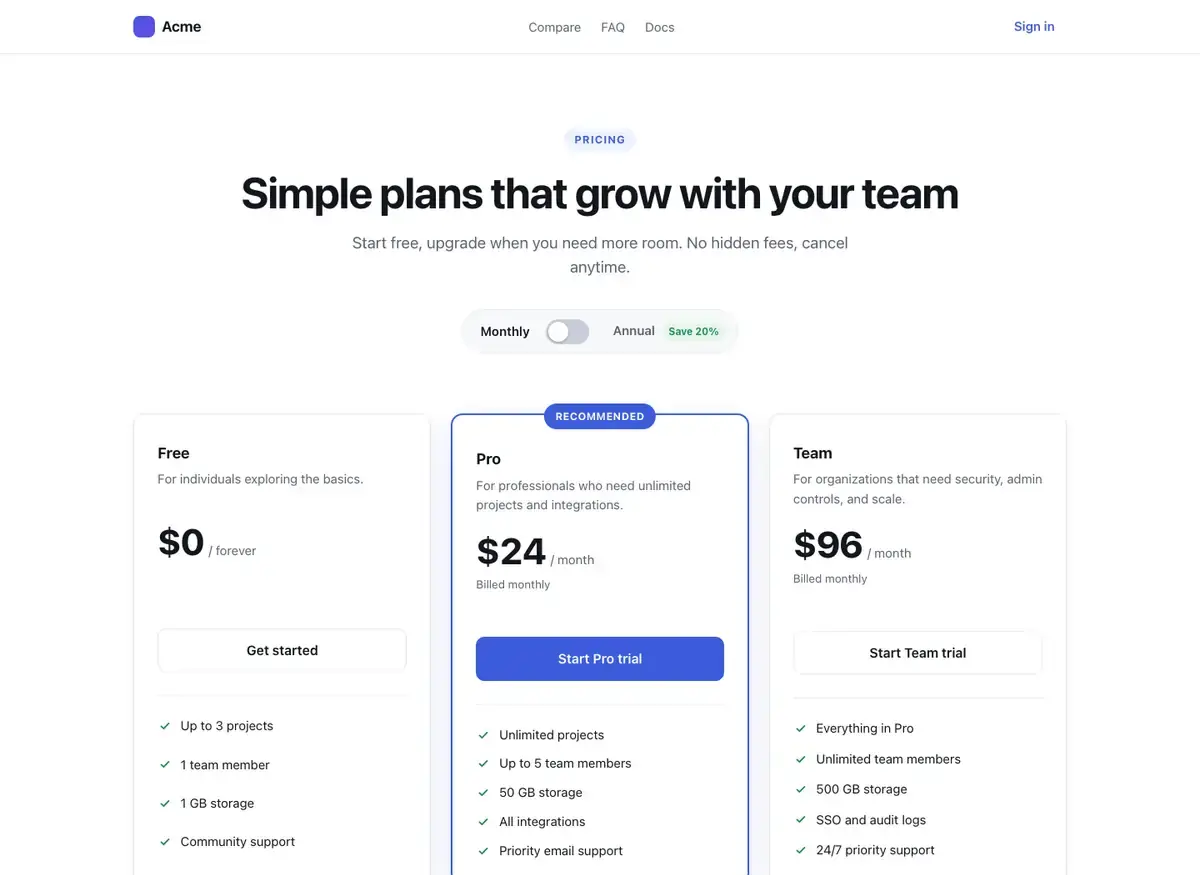
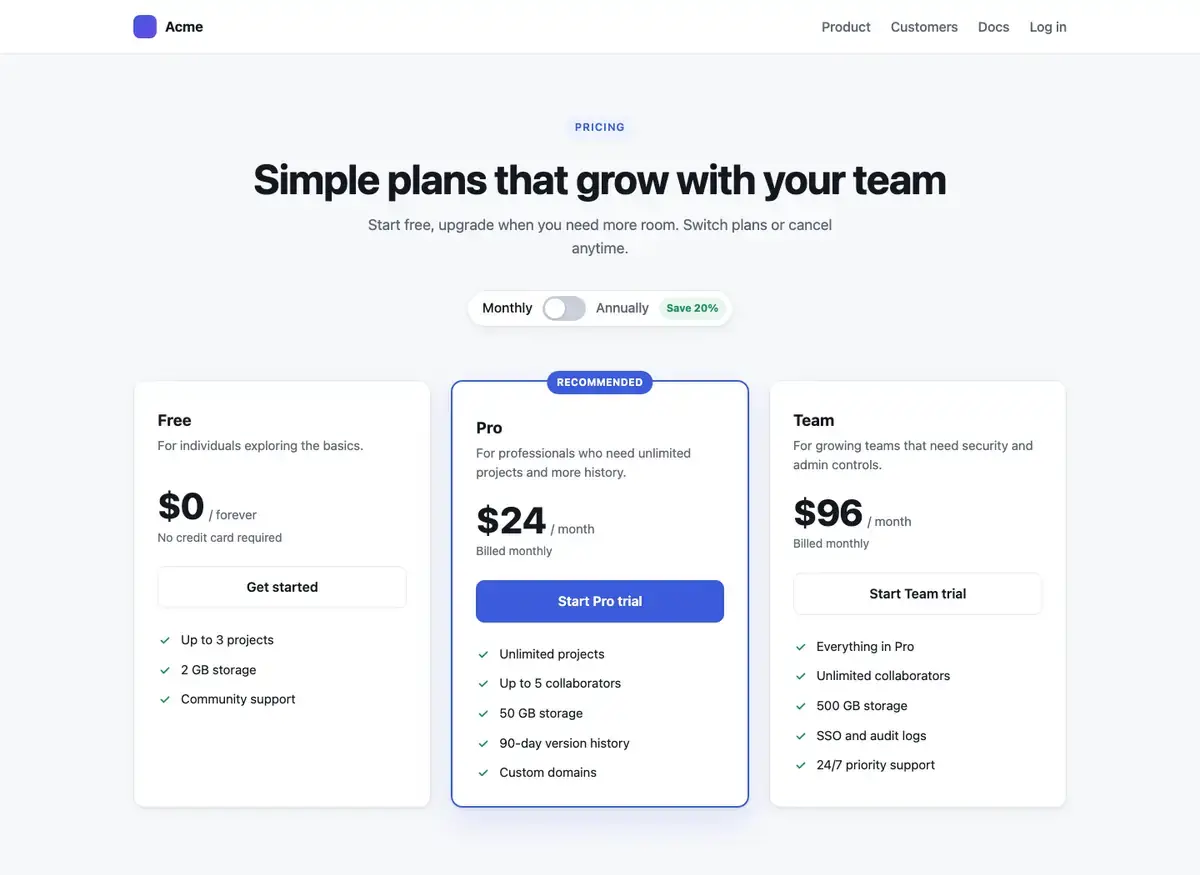
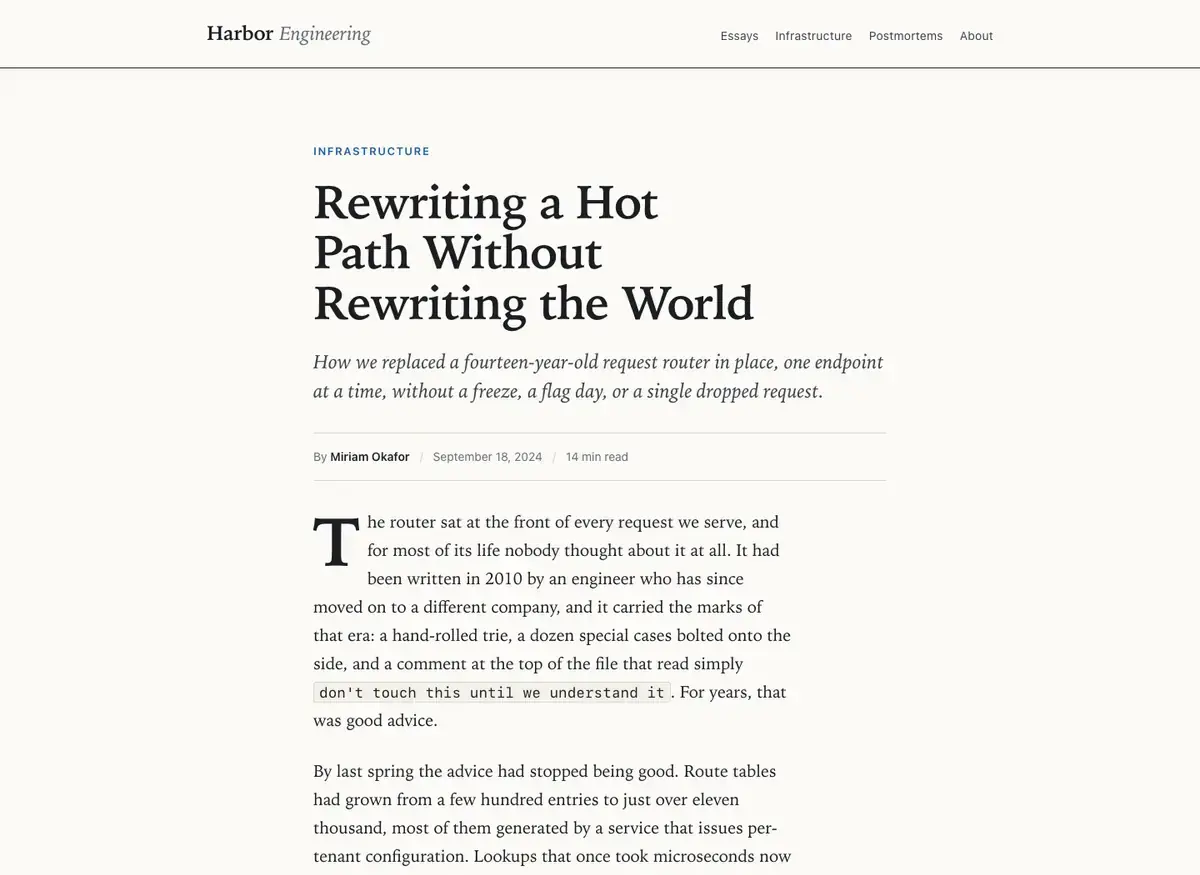
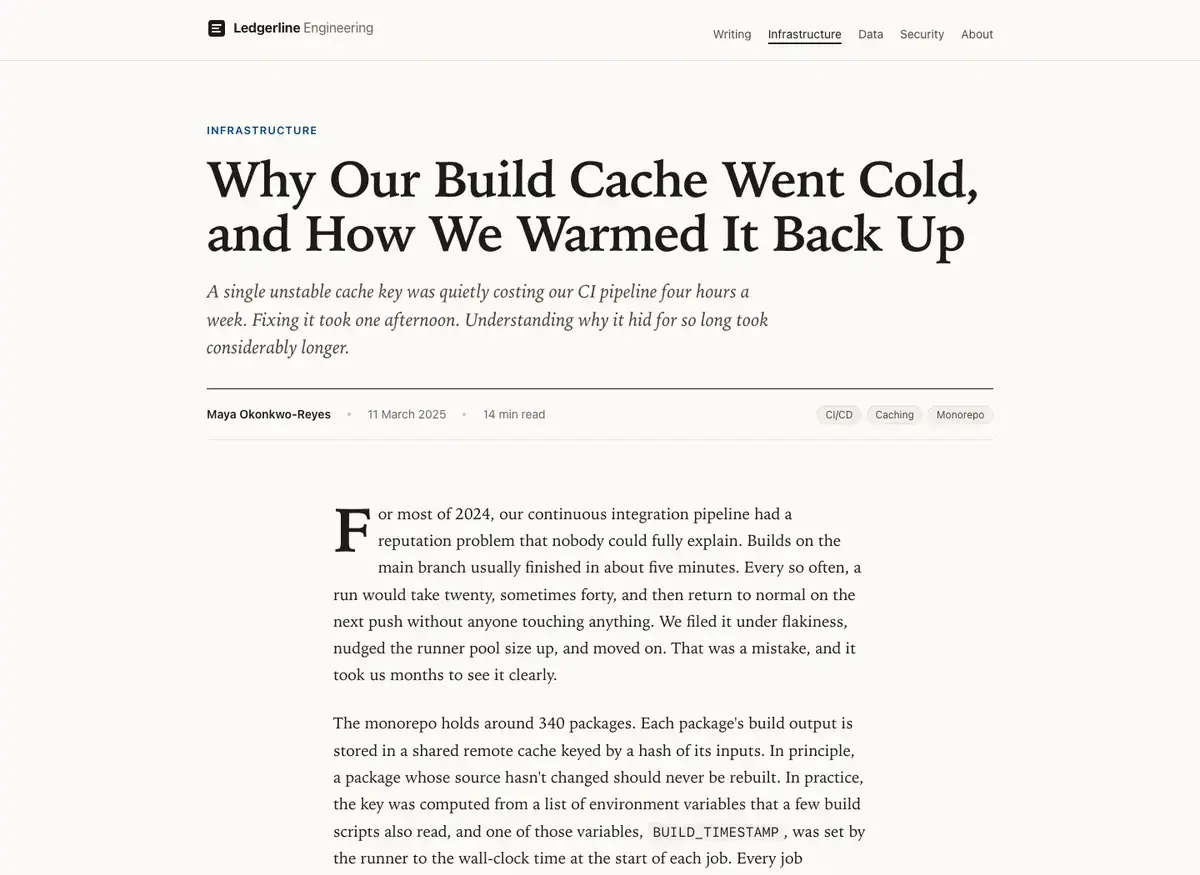
Of its 10 judged pages, the one the judge graded highest and the one it graded lowest, with the judge's top findings on each, most severe first.
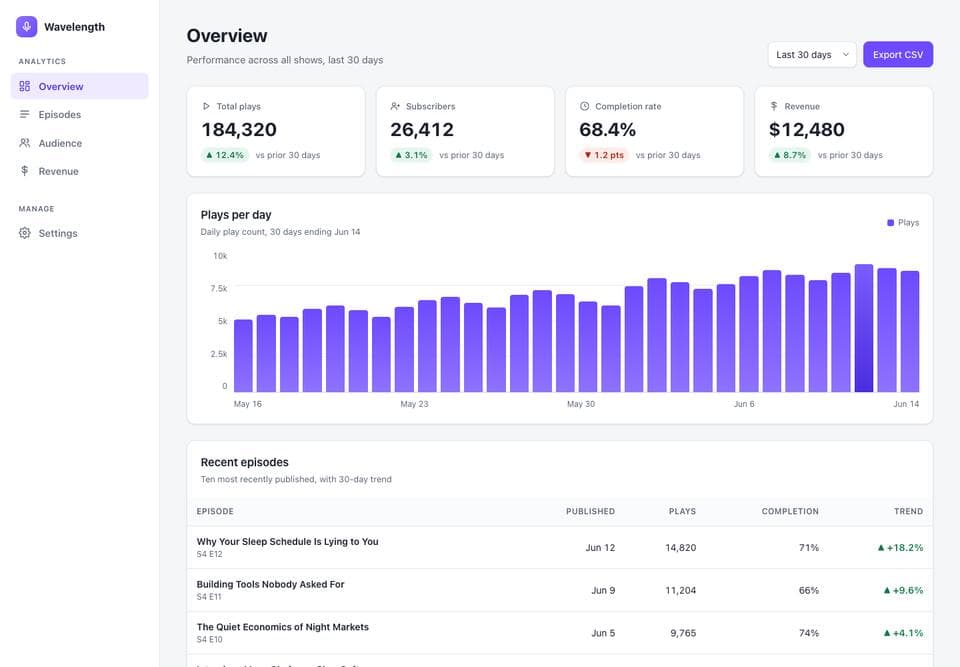
Best: Dashboard96.6
- Right-column stat cards clipped mid-labelSerious
- Excessive dead space below episode tableModerate
- Redundant 'vs prior 30 days' repeated four times in stat cardsModerate
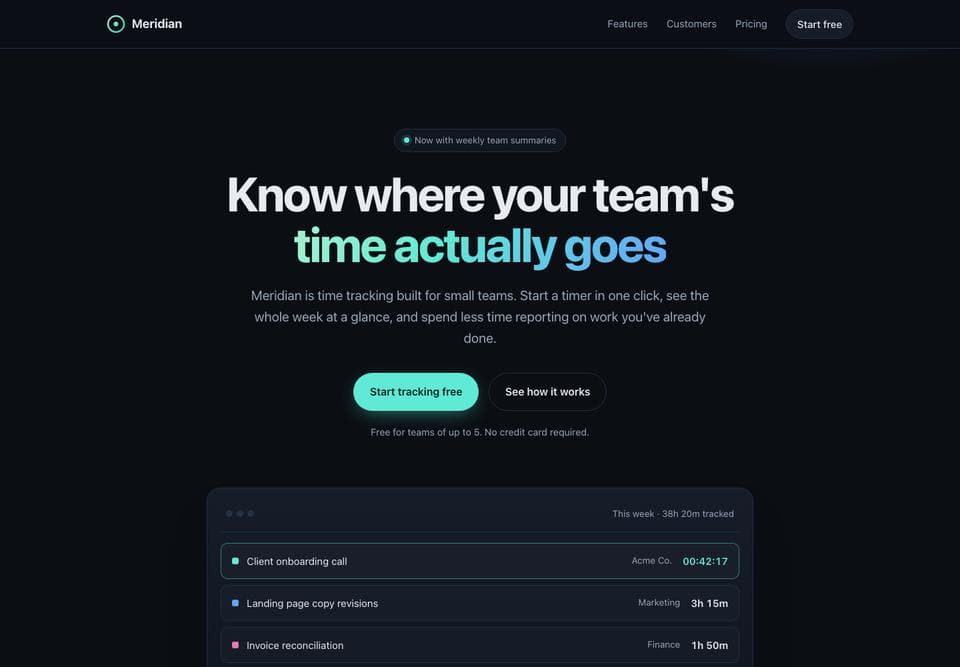
Worst: Landing5.8
- Two-color gradient headline splits accent budget across two hues simultaneouslySerious
- Inconsistent time format between active row and completed rows in preview widgetSerious
- Headline span breaks across lines awkwardly, splitting gradient from anchor textSerious
Head to head
Claude Haiku 5.5 against every other model: the paired difference in Index points, and whether the 95% interval on it clears zero.
- vs GPT-6 Astra-26.8Clearly behind
- vs Claude Fable 5.1-25.0Clearly behind
- vs GPT-6.1 Sol-23.6Clearly behind
- vs Grok 4.7-23.2Clearly behind
- vs GPT-6.1 Terra-18.6Clearly behind
- vs Mistral Large 4-8.9Inside the noise
- vs GLM 5.3-8.8Inside the noise
- vs Claude Sonnet 5.5-8.2Inside the noise
- vs Claude Opus 5.5-7.9Clearly behind
- vs GPT-5.6 Sol-7.2Inside the noise
- vs GPT-6 Luna-4.1Inside the noise
- vs Kimi K3-1.4Inside the noise
- vs Kimi K3.1 Pro+2.9Inside the noise
- vs GLM 5.3 Prime+4.9Inside the noise
- vs Claude Fable 5+7.0Inside the noise
- vs DeepSeek V4 Pro+27.1Clearly better
- vs MiMo V2.6 Pro+27.9Clearly better
- vs Claude Opus 4.8+37.0Clearly better
- vs Gemini 4 Argon+43.5Clearly better
- vs MiniMax M3+50.4Clearly better
- vs Gemini 3.8 Flash+52.5Clearly better
- vs Qwen 3.8 Max+53.2Clearly better
- vs Qwen 3.8 Max Prime+54.6Clearly better
- vs Muse Spark Open+59.6Clearly better
- vs Muse Wonder+60.7Clearly better
The other models
Season 0.6.1 of the Rams Index, in board order.
- GPT-6 AstraRank 1 · OpenAI91.0
- Claude Fable 5.1Rank 2 · Anthropic89.2
- GPT-6.1 SolRank 3 · OpenAI87.8
- Grok 4.7Rank 4 · SpaceXSI87.4
- GPT-6.1 TerraRank 5 · OpenAI82.8
- Mistral Large 4Rank 6 · Mistral73.1
- GLM 5.3Rank 7 · Zhipu73.0
- Claude Sonnet 5.5Rank 8 · Anthropic72.4
- Claude Opus 5.5Rank 9 · Anthropic72.1
- GPT-5.6 SolRank 10 · OpenAI71.4
- GPT-6 LunaRank 11 · OpenAI68.3
- Kimi K3Rank 12 · Moonshot65.6
- Kimi K3.1 ProRank 14 · Moonshot61.3
- GLM 5.3 PrimeRank 15 · Zhipu59.3
- Claude Fable 5Rank 16 · Anthropic57.2
- DeepSeek V4 ProRank 17 · DeepSeek37.1
- MiMo V2.6 ProRank 18 · Xiaomi36.3
- Claude Opus 4.8Rank 19 · Anthropic27.2
- Gemini 4 ArgonRank 20 · Google20.7
- MiniMax M3Rank 21 · MiniMax13.8
- Gemini 3.8 FlashRank 22 · Google11.7
- Qwen 3.8 MaxRank 23 · Alibaba11.0
- Qwen 3.8 Max PrimeRank 24 · Alibaba9.6
- Muse Spark OpenRank 25 · Meta4.6
- Muse WonderRank 26 · Meta3.5

Frameworks